Grok 4.7 Beats Claude Fable And GPT-5.6 Sol On Legal And Engineering At A Fifth Of The Price
0:00 / 0:57
News
Grok 4.7 Beats Claude Fable And GPT-5.6 Sol On Legal And Engineering At A Fifth Of The Price
calendar_today Date:
schedule Duration: 0:57
visibility Views: 24
database
Summary Report
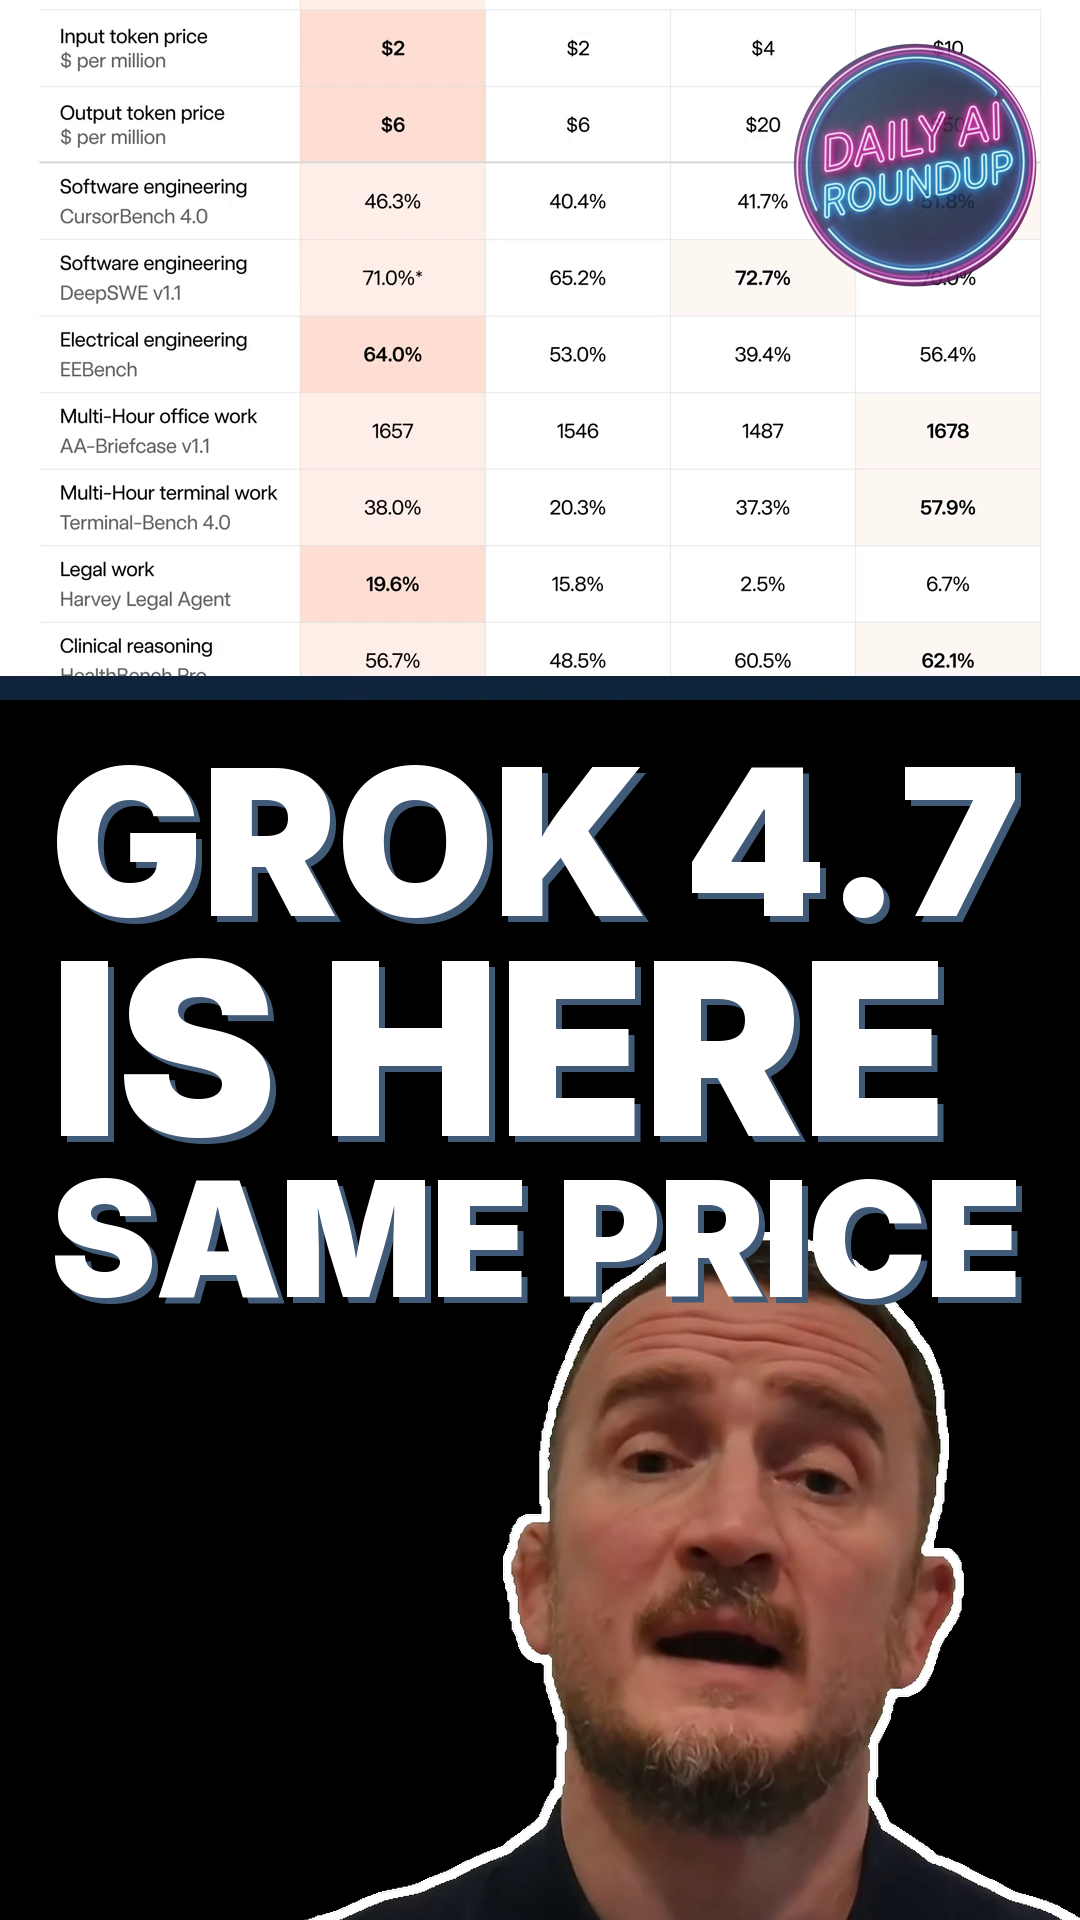
Grok 4.7 keeps Grok 4.6's pricing and leads the frontier on electrical engineering and legal agent work at a fifth of Claude Fable's price.
- 01. EEBench 64.0% vs Fable 5.1 56.4% and GPT-5.6 Sol 39.4%; Harvey Legal Agent 19.6% vs 6.7% and 2.5%
- 02. $2 in and $6 out per million tokens vs $10/$50 for Fable and $4/$20 for Sol; Fable still leads coding, terminal work and clinical reasoning
SpaceXAI has released Grok 4.7 at the same price as Grok 4.6: $2 per million input tokens and $6 out. On SpaceXAI's own chart it leads on EEBench, an electrical engineering test, with 64% against 56.4% for Claude Fable 5.1 and 39.4% for GPT-5.6 Sol, and on Harvey's legal agent benchmark with 19.6% against 6.7% and 2.5%. Multi-hour terminal work jumps from 20.3% to 38%. Fable still wins CursorBench, Terminal-Bench and clinical reasoning, but costs $10 in and $50 out.
Meta Data
Tag:
Model: